OPEN SOURCE PLATFORMS
Valkey Was the Easy Choice. Operating It Was the Real Decision
What a platform team learned when package provenance, cluster slots and day-two ownership arrived together.
The proposal sounded simple: adopt Valkey, keep the protocol the applications already understood, and regain control of the platform roadmap. The first architecture review lasted twenty minutes. The operating review lasted three weeks.
Start with one workload | Scale into a complete platform | Open Source Freedom | Enterprise-Grade Operations.
Published | July 2026
The decision behind the technology decision
The proposal sounded simple: adopt Valkey, keep the protocol the applications already understood, and regain control of the platform roadmap. The first architecture review lasted twenty minutes. The operating review lasted three weeks.
Teams agreed on the engine but not on the service: which packages were approved, who owned ACLs, what proved complete slot coverage, and how a failed upgrade would be reversed without improvisation.
| Open Source Freedom Needs An Operating Contract. |
The turning point
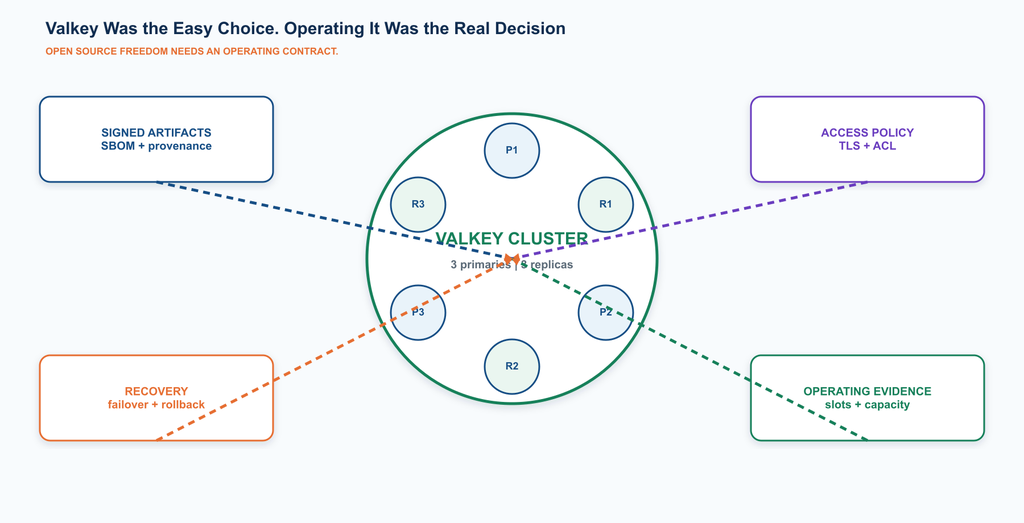
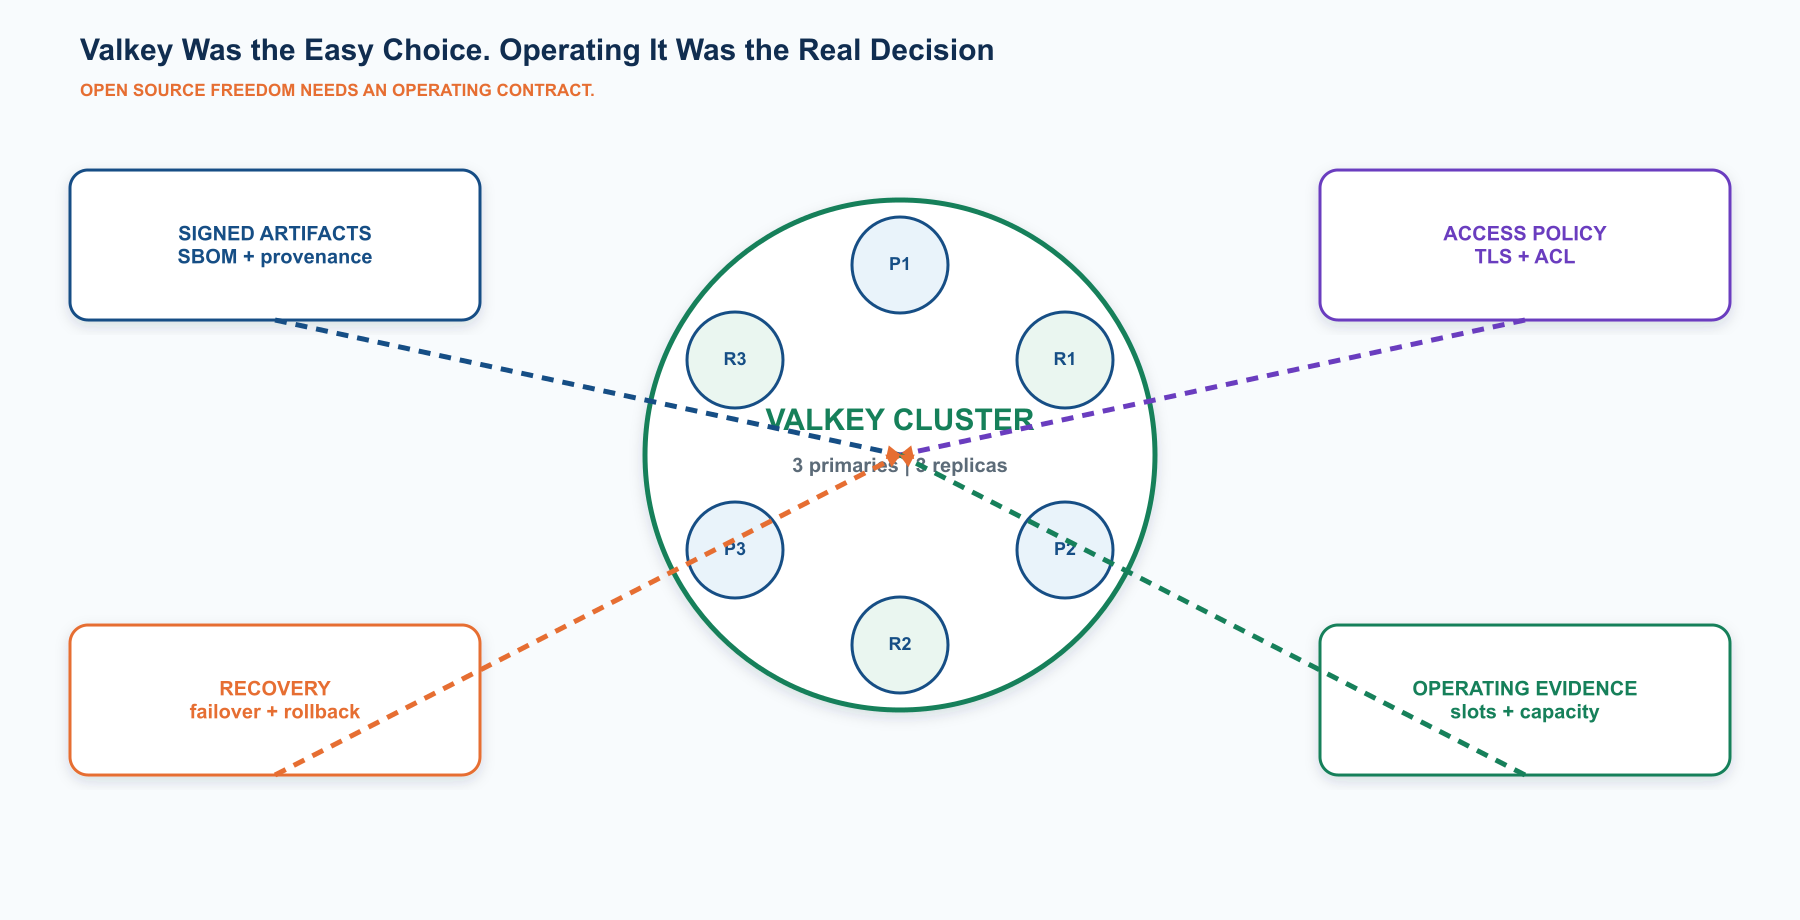
The platform became real when those questions were expressed as policy before deployment. Signed artifacts, SBOM evidence, topology validation, memory headroom and rollback boundaries became part of one release record.
The team used OSS Manager to make production Valkey lifecycle with open-source package governance reviewable and repeatable. The engine still owned its native behaviour; the control plane made intent, prerequisites, execution and evidence visible to the people responsible for the service.
What had to become explicit
- The service boundary: A declared Valkey standalone, Sentinel, or cluster topology is provisioned from approved packages with TLS, ACL, persistence, monitoring, backup, and rollback controls.
- The operational controls: signed package catalog, SBOM evidence, topology validation, ACL and TLS, persistence policy, memory limits, failover rehearsal, and rollback artifacts.
- The capacity conversation: key count, average and maximum value size, throughput, TTL distribution, persistence mode, replication factor, resharding headroom, and maintenance reserve.
- The human boundary: who may observe, who may approve, who may execute, and who decides whether the application is ready.
The architecture that changed the conversation
The diagram is deliberately centred on the decision the team had to make. It is not a product inventory. It shows where authority sits, what crosses the boundary, and where a failed assumption must stop the workflow.
The practical design choices
| Decision | Why it matters | Evidence |
| Artifact | Known origin and dependencies | Signature and SBOM |
| Topology | No missing slots or weak replica plan | Coverage and health |
| Change | Upgrade remains reversible | Preflight and rollback record |
| Access | Operators need bounded privileges | ACL convergence and audit trail |
| Capacity | Memory pressure changes failure behaviour | Headroom, eviction and fragmentation evidence |
These choices are intentionally small enough to review and test. They keep the architecture tied to operating behaviour instead of allowing a visually impressive diagram to hide unclear ownership.
What OSS Manager changed - and what it did not
OSS Manager brought discovery, planning, guarded execution and normalised status into one path for Valkey. It did not replace the engine's correctness model or the application's responsibility for data semantics.
- Before change, validate versions, hosts, identities, artifacts, topology and the recovery boundary without mutating the service.
- During change, persist progress, expose stop conditions and prevent a partial result from being mistaken for success.
- After change, observe availability; operations per second; p95 latency; memory; evictions; replication lag; cluster slots; failover; persistence and backup age and run representative application journeys, not only process checks.
- For recovery, protect the last known-good authority and require an explicit decision before promotion, rollback or destructive cleanup.
The failure modes worth rehearsing
The test plan should make room for unsigned artifact, incompatible module, slot imbalance, failover loop, memory pressure, stale replica, persistence error, and client routing mismatch. The purpose is not to produce a longer checklist. It is to learn whether operators can recognise the failure and choose the safe next action while the evidence is incomplete.
A human operating model
L1 operators need a plain-language answer to what is healthy, what is delayed and whether a change is in progress. Platform engineers need topology and evidence. Application owners need to know what users will experience. A useful platform connects those views without giving every person the same privileges.
| Valkey delivered open-source choice. The operating contract made that choice sustainable across environments and teams. |
Where this pattern earns its place
Media and OTT
This pattern is relevant where teams need regional continuity, burst traffic, low-latency serving and predictable recovery. The architecture must still be adjusted for local data classification, recovery objectives, workload shape and application behaviour.
Retail
This pattern is relevant where teams need campaign peaks, catalogue freshness, transaction continuity and rapid rollback. The architecture must still be adjusted for local data classification, recovery objectives, workload shape and application behaviour.
Telecom
This pattern is relevant where teams need high event volume, distributed operations, identity boundaries and service assurance. The architecture must still be adjusted for local data classification, recovery objectives, workload shape and application behaviour.
The lesson we would carry into the next project
Valkey delivered open-source choice. The operating contract made that choice sustainable across environments and teams.
The strongest open-source platforms are not the ones with the most automation. They are the ones where automation makes ownership, risk and recovery easier for people to understand.
| Start with one workload. Prove the operating model. Then scale it into a complete platform. |
